Applied AI · 20 Oct 2026
Slop in, slop out: the data nobody labeled
What happens when models train on, or retrieve from, their own output. How the rare cases disappear first, and the labelling and dedup that keep a corpus clean.
Emin C. Homalioglu · 4 min read · Updated 03 Nov 2026
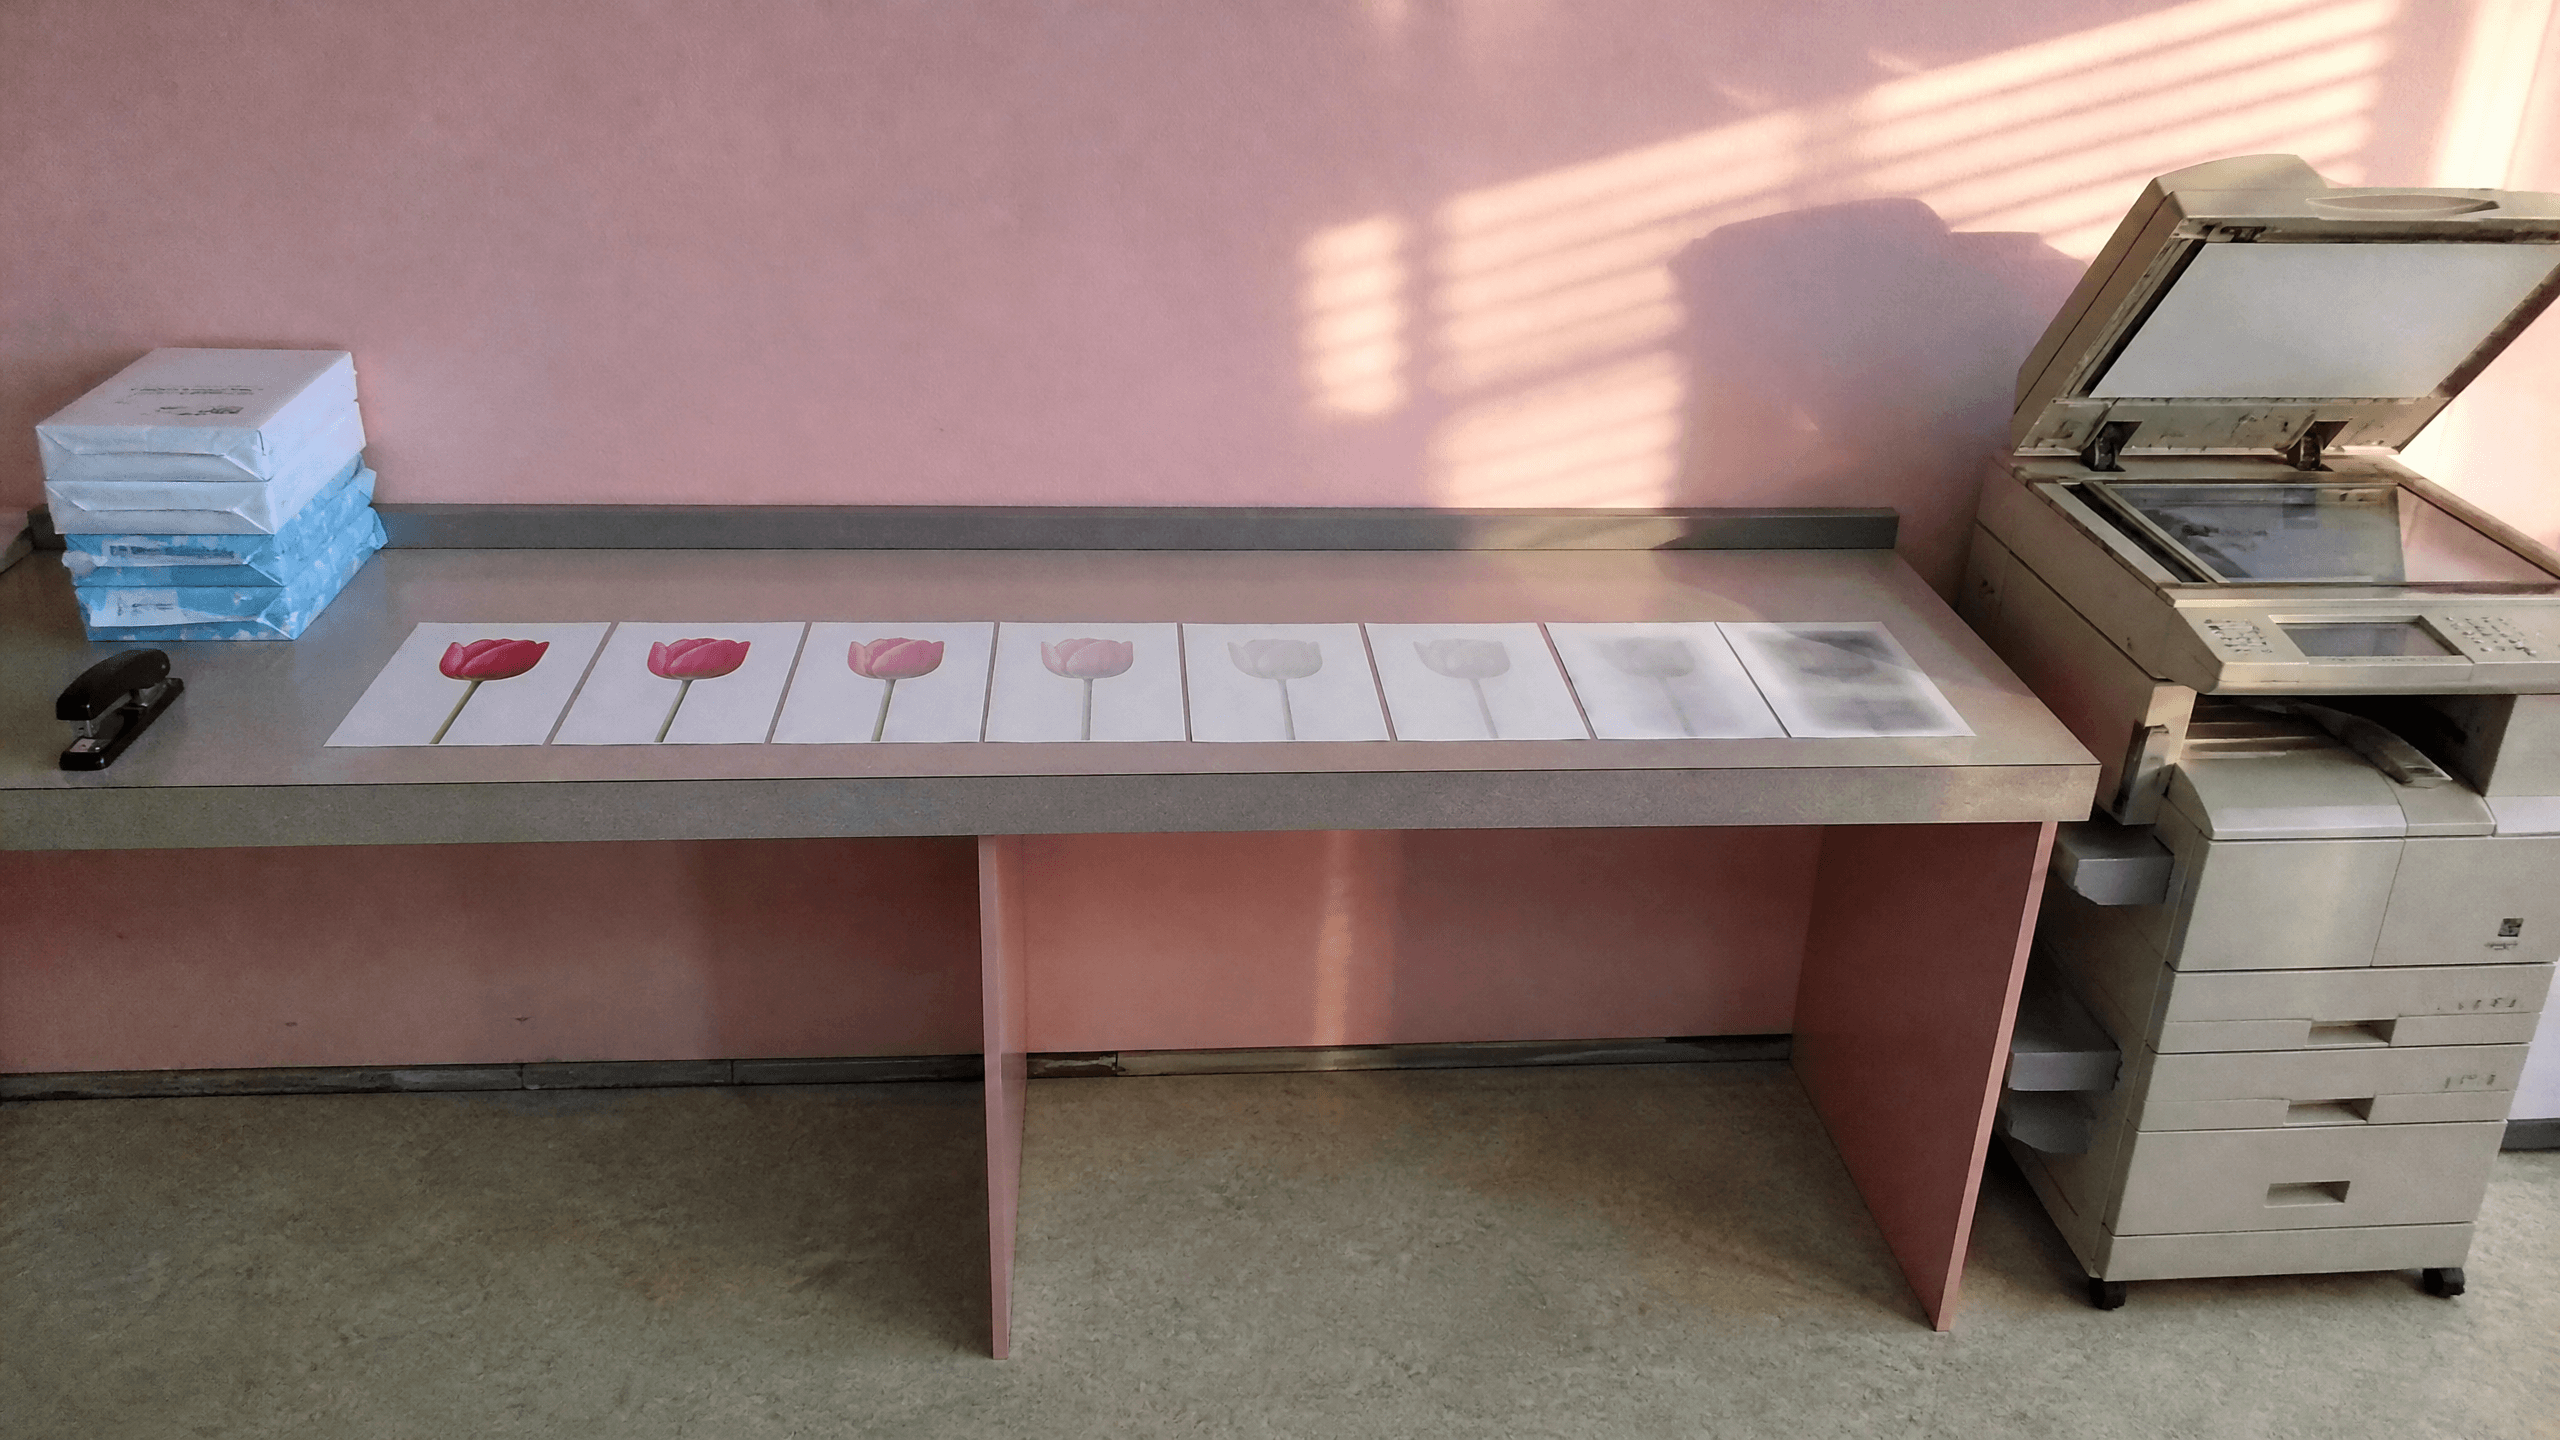
A model trained on text that other models wrote loses range, and it loses it at the edges first. The same thing happens, more quietly, to a search index that fills up with generated pages.
The short version
If your company uses AI on top of its own documents, as a knowledge base, a support bot or an internal search:
- Generated texts stored next to your originals will, over time, be found instead of them.
- Every stored item needs a label: written by a person, by a model, or by a model editing a person's text.
- Ask whoever runs the system: can it name, for any answer, the original document it came from?
The rare cases go first
Language data has a body and edges. The body is the common phrasing and the well-known facts. At the edges sit the unusual case, the specialist term, the rare correct answer. A model learns the body well and the edges thinly.
When the next model trains on the output of the last one, it sees the body even more strongly and the edges even more thinly, because generation favours the likely. Shumailov and colleagues showed this in Nature in 2024: models trained repeatedly on their own output lose the tails of the distribution first and end up converging on a narrow middle (Shumailov et al., 2024). They call it model collapse.
The same loop in a knowledge base
You do not need to train a model to hit this. A retrieval system has the same shape:
- Documents go into an index.
- A model reads some of them and writes summaries, answers and new pages.
- Those outputs are stored in the same place.
- Search now returns the summaries, since they are shorter and match more queries.
- The next summaries are written from the earlier summaries.
After a few rounds the index answers from summaries of summaries. Exact figures get rounded, qualifications fall away, and a claim that was hedged in the source arrives as a flat statement. No single step looks wrong. The failure sits in the loop.
The public web has the same problem at scale. Generated pages are cheap, match common queries well and are written from other pages. A crawler that cannot tell them apart takes the average for consensus.
What keeps a corpus clean
Record provenance at write time. Every stored item records whether a person wrote it, a model wrote it, or a model edited a person's text, and from which sources. A column in the table is enough. A label added later is a guess.
Retrieve sources, not derivatives. The original documents stay the authority. Summaries are generated on demand or kept in a separate index that never mixes with the evidence. If a derivative has to be findable, it ranks below its source, and the source is shown.
Remove near-duplicates. Generated pages on the same topic share structure and wording without being identical. Fuzzy methods such as MinHash over word sequences, or clustering by embedding distance, find them. Keep one item per cluster, or a topic with fifty rewrites outvotes a topic with one careful page. The effect is documented for training data too: deduplicated data gives models that repeat memorised text less often and train more efficiently (Lee et al., 2021).
Keep a human-written core. A fixed, versioned set of verified material that is never overwritten and never generated from generated text. You measure everything else against it, and you can rebuild from it.
Our own writing follows the same rule. Every article in this Laboratory has exactly one source in our internal knowledge base, and the website gets a copy. Changes happen at the source and flow outward, never back.
Test with data the loop has not touched. If the test set came out of the same pipeline, it shares the pipeline's blind spots and reports that all is well. Hold back cases labelled by people, deliberately including rare ones, and score the rare ones separately.
Measure diversity as well as accuracy. Vocabulary size, distinct word sequences, the number of different answers to a fixed set of questions. Accuracy on common questions stays high while the edges disappear, so an accuracy number alone will not warn you.
Where to start
Add a provenance column today and fill in what you can, even if the first value is "unknown". Everything else on this list depends on it.
A corpus that cannot say where each item came from can only be cleaned by starting over.
20 Oct 2026 · Emin C. Homalioglu